Product and market research
Read product details, availability, and prices from rendered pages. Use geographic proxy targeting when your research needs to reflect a particular location.
Web Scraping
Collect data from pages that need JavaScript, navigation, and real interaction. Use your existing Playwright or Puppeteer extraction logic on current browsers with authentic hardware signals and the right network route for each target.
Built for Web Scraping
Use a full browser when the information you need appears after a page renders, a user interacts, or the next page loads.
Read product details, availability, and prices from rendered pages. Use geographic proxy targeting when your research needs to reflect a particular location.
Navigate pagination, filters, and interaction-heavy listings with familiar browser APIs. Shape the results in your own extraction code.
Collect the mobile version of a site on physical mobile hardware. Use real device signals rather than relying only on a changed user agent or viewport.
The Cloud Dev Tools difference
Browser access is more than an endpoint. These capabilities work together underneath your code, across AI agents, scraping, automation, and testing.
Automation libraries can leak objects that a website’s web application firewall detects. Our own firewall sits between libraries such as Puppeteer and Playwright and the browser to prevent those detectable object leaks.
Your library → CDT firewall → Browser
Every browser instance has a native GPU for hardware rendering. WebGL, canvas, video, and page composition use real graphics hardware, with actual consumer CPU and RAM values reported in JavaScript.
Consumer CPU · Real RAM · Native GPU
Run desktop browsers on consumer hardware or choose physical mobile devices. Mobile sessions use an actual mobile browser environment rather than desktop emulation with a smaller viewport.
Real desktop hardware · Physical mobile
Choose datacenter, residential, or mobile proxies, city-level targeting, or bring your own proxy. The API’s domain-based routing keyword helps automatically select an appropriate proxy for your target website.
Domain-based routing · Flexible proxies
We run regular browsers and keep them up to date. TLS and protocol handshake parameters come from the browser itself, without tying your workflow to an older browser binary bundled with an automation library.
Up-to-date browsers · Native protocols
Mouse and keyboard events execute at the system level, through the same input path as real peripherals. Movements and keystrokes mimic human behavior instead of relying only on synthetic page events.
System-level mouse · System-level keyboard
From code to browser
Use Playwright or Puppeteer with a managed browser endpoint. Start with the connection details in the API documentation.
Read the integration documentationUse domain-based routing to help select an appropriate proxy, or choose datacenter, residential, mobile, or your own proxy.
Connect your script to a real browser, navigate the target, and read the page using your existing selectors and parsing logic.
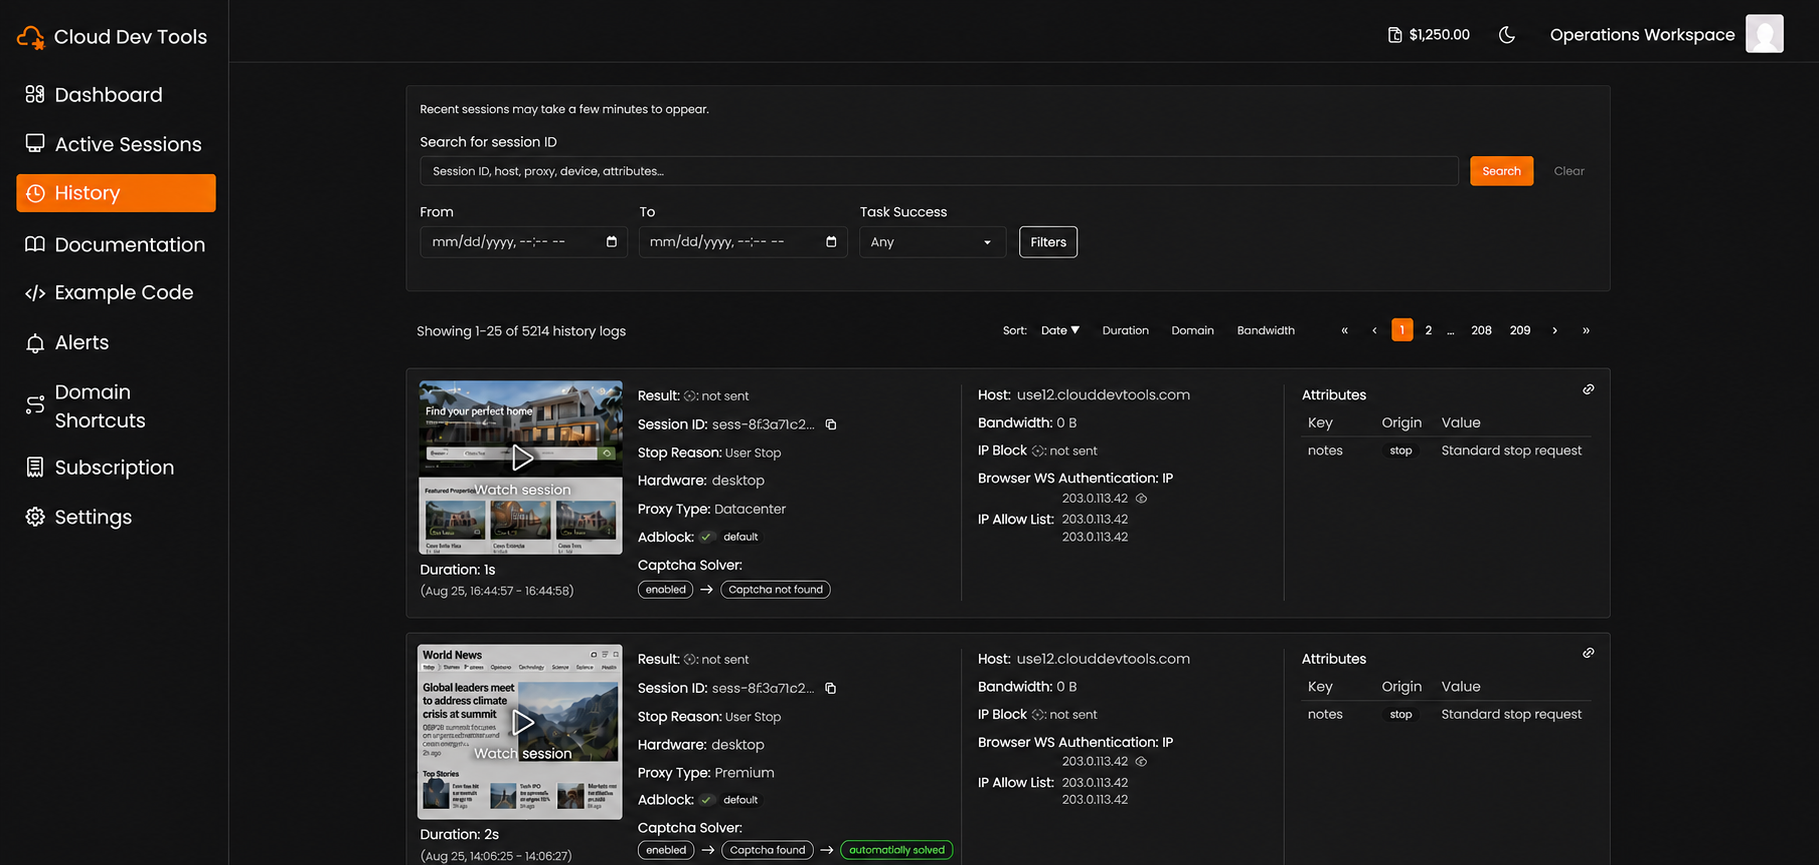
Review session logs, proxy details, and recordings to understand failed navigations or unexpected page content.
From development to investigation
The browser is only half the workflow. Develop in the portal, follow active sessions, and return to the evidence when something needs a closer look.
Let people and AI agents follow the browser as a workflow runs.
Find past sessions, inspect detailed logs, and review clear recordings.
Write and run tests in supported languages without local IDE or environment setup.
Use local AI models to help resolve difficult CAPTCHA challenges during a session.
Common questions
Use Playwright or Puppeteer to connect to a remote browser instead of launching a local one. Keep your navigation and extraction logic, and validate your script against the selected device profile.
Cloud Dev Tools supports datacenter, residential, and mobile proxies, city-level targeting, and bring-your-own proxy. Domain-based routing helps select an appropriate proxy for the target website.
No. Access depends on website policy, IP reputation, account state, configuration, and behavior. The platform also offers locally run AI models to help resolve difficult CAPTCHA challenges.
A complete browser foundation